AI execs may be too out of touch to build for the general public
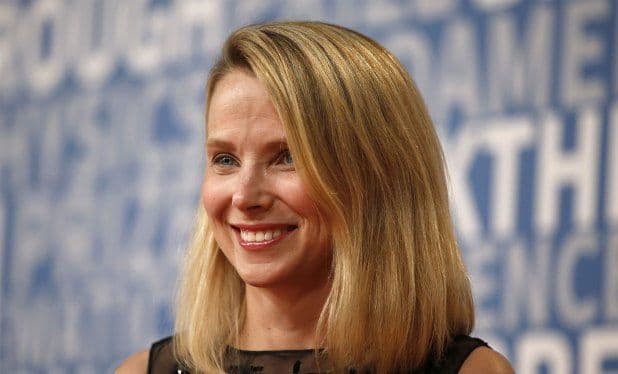
Former Yahoo CEO and early Google engineer Marissa Mayer is catching a lot of flak for how she uses AI. Inan interviewabout her new app Dazzle, an AI assistant that learns from your camera roll, Mayer poses what she believes is an impressive flex for the product: It helped her come up with three bullet points about her 10-year-old daughter for a birthday presentation at school, describing her as “empathetic, creative, and an animal lover.” It’s a vague description, like a generic horoscope — it could probably describe a lot of 10-year-olds. Some onlookers, like progressive activist Leah Greenberg,marveledthat “the fact that Marissa Mayer would voluntarily disclose this to a reporter is a pretty good demonstration of how deeply the culture of Silicon Valley has diverged from the rest of humanity.” "She thought it was perfect."www.nytimes.com/2026/10/25/s… Perhaps Mayer drew so much backlash because we have repeatedly observed sheltered billionaires suggest that we outsourcechild-rearing— one of life’s greatest tests of patience, humility, and kindness — to a computer that isincapable of understandinghuman emotion. We’ve been primed for this frustration. Last year, OpenAI CEO Sam AltmantoldBored Ape ownerand late night host Jimmy Fallon on national television, “I cannot imagine … figuring out how to raise a newborn without ChatGPT.” The public didn’t love that comment, either, but Altman wasn’t fazed by thenegativefeedback. A few months ago, he said on X that a “cool use case” of ChatGPT Work would be creating a podcast that talks about your kids’ upcoming birthdays or soccer games and “explain[s] your kids’ interests.” (He was brutallyratioedwithcommentslike, “What if you just talked to your children?”) After publication, Mayer defended herself in a longX post. She claims she was not relying on Dazzle to explain her child to her, but rather, she was testing what her prototype could do — it resurfaced photos of “forgotten kindergarten projects,” like a “snake devenomer” or “sandcat playground,” illustrating her daughter’s creativity and care for animals. Fair enough. But Mayerremarksin the same interview that people could also use her AI to outsource the mental load of “figuring out the theme for your child’s birthday party.” She says she’s used her app to plan a playdate for her daughter, book family activities on vacation, and decide what to be for Halloween. She even proposes that her AI assistant could coordinate plans with her husband’s AI assistant. When the reporter asks her if it’s depressing to imagine this “frictionless future … planned by AI,” Mayer replies, “I haven’t really thought that through.” These leaders seem to write off the naysayers as part of a small, angry fringe group. Yet a Pew Research Centerstudyreports that 50% of U.S. adults think that AI will reduce people’s ability to form meaningful relationships. Only 5% of respondents said AI would make it easier to build these connections. Meta CEO Mark Zuckerberg, however, joins his Silicon Valley kin in envisioning a world where our social needs are met via AI. “The average American I think has, it’s fewer than three friends, three people they’d consider friends, and the average person has demand for meaningfully more, I think it’s like 15 friends,” Zuckerberg said last year on apodcast. “The average person wants more connectivity, connection than they have.” Zuckerberg predicts that it will become more socially acceptable to outsource our emotional needs to AI therapists or even AI romantic partners. “There are all these things that are better about physical connections when you can have them,” he added. “But the reality is that people … feel more alone a lot of the time than they would like.” Zuckerberg goes on to explain how virtual-reality embodiments of AI avatars are only growing more realistic. Meta seems to be more keen on improving our relationships with these approximations of humans, rather than between the actual billions of humans who use its platforms each day. Maybe part of this stems from the culture of the tech industry, which prizes efficiency. People try to biohack their own bodies by optimizing theirsleep scheduleswith health trackers or injecting unregulated “peptide stacks” to maximize their productivity. If you’re building electric vehicles or computer chips, then sure, efficiency is a clear north star. But our relationships with other people are not a tech product that we’ve been challenged to ship with as little capital as possible. Human relationships are inherently messy, but our connections with one another can be what gives our lives meaning. When we delegate those interactions to computers, we surrender the difficult, yet fulfilling experience of being people.